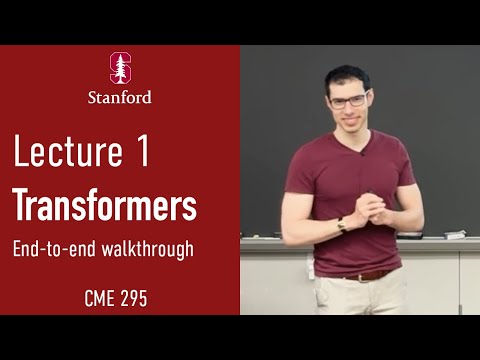
For more information about Stanford’s graduate programs, visit: To follow along with the course schedule and syllabus, visit: Chapters: 00:00:00 Introduction 00:03:36 Pretraining 00:10:33 Cross-entropy loss 00:17:15 Data mixtures 00:22:18 Midtraining 00:23:41 Long context training 00:31:47 Supervised finetuning (SFT) 00:40:15 Low-Rank Adaptation (LoRA) 00:46:37 Preference tuning 00:54:44 Bradley-Terry formulation 01:01:49 Reinforcement Learning from Human Feedback (RLHF) 01:05:38 Direct Preference Preference Optimization (DPO) 01:12:08 Reasoning 01:20:56 Group Relative Policy Optimization (GRPO) 01:23:31 On-Policy Distillation (OPD) 01:27:47 End-to-end example Afshine Amidi is an Adjunct Professor at Stanford University. Shervine Amidi is an Adjunct Professor at Stanford University. Follow the playlist:
- 👁️ 62.4 тыс
- 📅 1 неделя назад